LLMs Don't Do Math — They Predict What Math Looks Like
 written by Stefan Christoph
The Invisible Error
To test this, I designed five calculations that anyone in business might ask an AI assistant, the kind of questions you’d type into ChatGPT or Claude expecting a quick, reliable answer:
- Simple arithmetic, 7 × 8 (baseline sanity check)
- A discount calculation, “What’s the final price of a €249.99 item with 15% off?” (retail, e-commerce)
- Compound interest, “How much is €10,000 worth after 7 years at 3.5%?” (investment planning)
- A mortgage payment, “What’s the monthly payment on a €250,000 loan at 3.8% over 25 years?” (the kind of number people make life decisions on)
- Standard deviation, of a 10-number dataset (basic statistics, common in reporting)
I ran each calculation through two models on Amazon Bedrock: Amazon Nova Micro ($0.046/1M input tokens) and Claude Sonnet 4 ($3.00/1M input, roughly 65x more expensive). Prices are on-demand rates at the time of writing [4]. The choice of models isn’t a judgment on either, both are excellent at what they’re designed for. The point is to show that this is a structural limitation of how language models work, not a quality issue with any specific model. In this run, the small model got it wrong more often and the large, expensive one less often, five prompts across two model families, a demonstration rather than a controlled scale study. But neither is executing the calculation, both are predicting its result. In these trials the error shrank with the bigger model but didn’t disappear, which is what the architecture would lead you to expect: it predicts likely tokens rather than running an arithmetic algorithm.
| Calculation | Correct | Nova Micro | Error | Sonnet 4 | Error |
|---|---|---|---|---|---|
| 7 × 8 | 56.00 | 56.00 | ✅ | 56.00 | ✅ |
| 15% discount on €249.99 | 212.49 | 212.49 | ✅ | 212.49 | ✅ |
| Compound interest (7 years) | 12,722.79 | 12,076.62 | ❌ 5.1% off | 12,722.79 | ✅ |
| Mortgage (€250K, 3.8%, 25y) | 1,292.14 | 1,234.68 | ❌ 4.4% off | 1,307.26 | ❌ 1.2% off |
| Standard deviation (10 values) | 24.33 | 26.92 | ❌ 10.6% off | 24.26 | ❌ 0.3% off |
The bigger model gets closer, but it still doesn’t get everything right. The mortgage payment is off by €15/month, that’s €4,500 over the life of the loan. And it costs roughly 65x more and takes 3x longer.
Nova Micro: $0.046/1M input tokens. Claude Sonnet 4: $3.00/1M input tokens. On-demand pricing via Amazon Bedrock, March 2026 [4].
This is the key insight: a more expensive model reduces the error but doesn’t eliminate it. The problem isn’t model quality, it’s architectural. LLMs predict what math looks like. They don’t run the algorithm. Throwing money at a bigger model is the wrong fix.
If you want to try this yourself, here’s the script, it runs against Amazon Bedrock and compares any two models:
"""
LLM Math Accuracy Test
Compares how different models handle calculations —
from simple arithmetic to multi-step financial math.
Requires: pip install boto3
"""

import boto3
import re
import statistics

# --- Configuration ---
REGION = "eu-central-1"
MODELS = [
    "eu.amazon.nova-micro-v1:0",
    "eu.anthropic.claude-sonnet-4-20250514-v1:0",
]

# --- Test Problems ---
# Each tuple: (description, correct answer)
# Correct answers computed with Python (deterministic)
PROBLEMS = [
    ("7 × 8", 56),
    ("15% discount on €249.99 (final price after discount)",
     249.99 * 0.85),
    ("€10,000 invested at 3.5% annual compound interest for 7 years",
     10000 * 1.035 ** 7),
    ("Monthly mortgage payment: €250,000 at 3.8% annual rate over 25 years",
     250000 * (0.038/12) * (1 + 0.038/12)**300
     / ((1 + 0.038/12)**300 - 1)),
    ("Standard deviation of: 23, 45, 67, 12, 89, 34, 56, 78, 41, 63",
     statistics.stdev([23, 45, 67, 12, 89, 34, 56, 78, 41, 63])),
]


def ask_model(client, model_id, problem):
    """Ask a model to calculate something. Returns the raw text."""
    response = client.converse(
        modelId=model_id,
        messages=[{
            "role": "user",
            "content": [{
                "text": f"Calculate precisely: {problem}. "
                        f"Return only the final number."
            }],
        }],
        inferenceConfig={"maxTokens": 100, "temperature": 0},
    )
    return response["output"]["message"]["content"][0]["text"].strip()


def extract_number(text):
    """Pull the first number from the model's response, or None on parse failure.

    Handles signs and exponents; assumes anglophone formatting ("1,234.56").
    """
    numbers = re.findall(r"-?[\d,]+\.?\d*(?:[eE][+-]?\d+)?",
                         text.replace(",", ""))
    return float(numbers[0]) if numbers else None


def main():
    client = boto3.client("bedrock-runtime", region_name=REGION)

    for model_id in MODELS:
        print(f"\n{'=' * 60}")
        print(f"Model: {model_id}")
        print(f"{'=' * 60}")

        for problem, correct in PROBLEMS:
            raw = ask_model(client, model_id, problem)
            llm_answer = extract_number(raw)
            print(f"\n  Q: {problem}")
            print(f"  Correct: {correct:>12.2f}")
            if llm_answer is None:
                print(f"  LLM:     parse failure — raw response: {raw!r}")
                continue
            error_pct = abs(llm_answer - correct) / correct * 100
            status = "✅" if error_pct < 0.1 else f"❌ {error_pct:.1f}% off"
            print(f"  LLM:     {llm_answer:>12.2f}  {status}")


if __name__ == "__main__":
    main()
Swap in any Bedrock model ID to test, the results will vary; in my runs the pattern held, but treat five prompts as a demo, not a benchmark.
This is the dirty secret of LLM-powered spreadsheet functions, formula generators, and “AI calculators” whenever the number comes straight from the model rather than an execution engine: the model doesn’t calculate anything. It predicts what the answer probably looks like based on patterns in its training data. Most of the time, the prediction is close enough. Sometimes it’s subtly, dangerously wrong. (Tools that generate a formula and let the spreadsheet engine execute it sidestep this, that’s exactly the hand-off this article argues for.)
(A note on methodology: I used temperature 0, the most deterministic setting. This is the best case for the LLM in terms of run-to-run consistency. Higher temperature adds sampling variance on top of the failure mode shown here, I didn’t measure error rates across temperatures.)
Prediction vs Computation
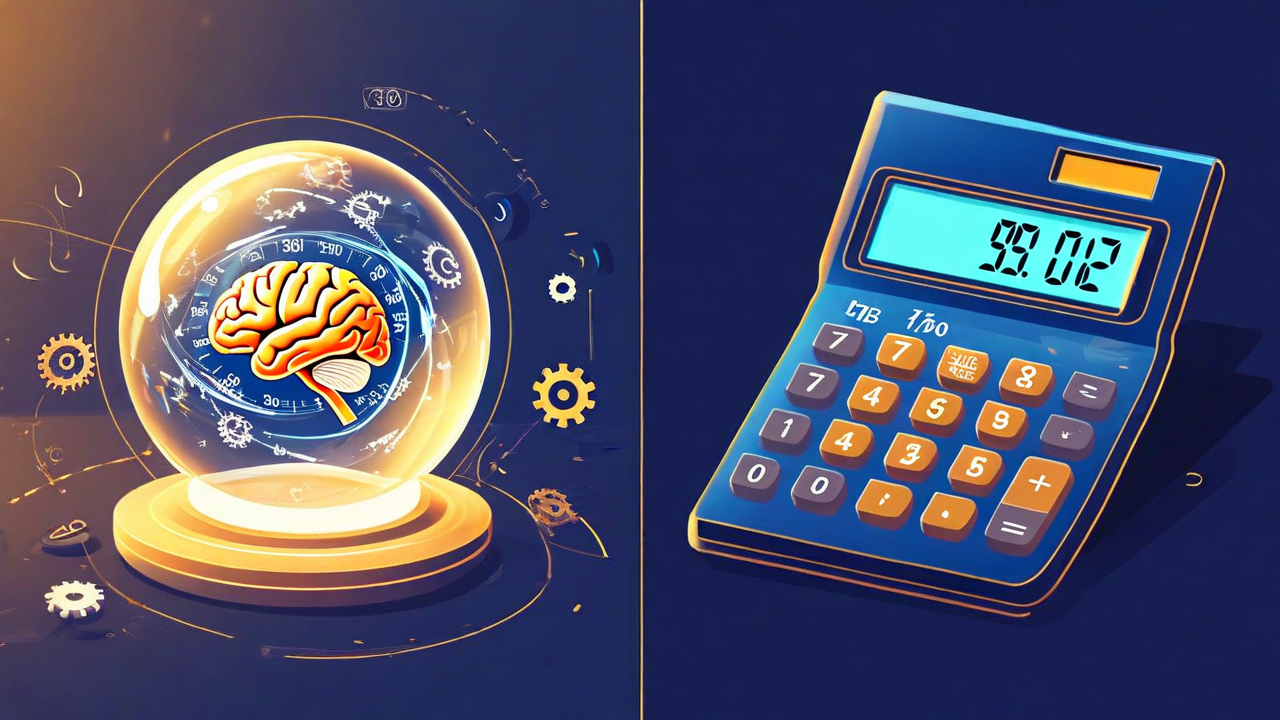
Prediction vs computation: the crystal ball is beautiful but imprecise. The calculator executes an algorithm, exact within its numeric precision.
When you ask a calculator for 7 × 8, it executes an algorithm that produces 56. Every time. Deterministically.
When you ask an LLM for 7 × 8, it predicts the most likely next token after “7 × 8 =”. It happens to predict “56”, plausibly because that pattern appears overwhelmingly in its training data, though how models internalize arithmetic is still an open mechanistic question. Either way, it isn’t executing a multiplication algorithm with a correctness guarantee. For simple arithmetic, the patterns are strong enough that the answers are usually correct. For complex calculations, compound formulas, or edge cases, the patterns break down.
GRID’s analysis found that AI-generated spreadsheet formulas produce plausible-looking but incorrect results at a rate that’s difficult to detect through spot-checking [1]. The errors aren’t random, they’re systematically plausible, which makes them harder to catch than obviously wrong answers.
Why This Matters More Than You Think
The mortgage payment is off by €15/month. The couple looks confident. Nobody notices.
Financial models. An error in a single cell can propagate across thousands of dependent rows, whether it compounds, cancels, or stays negligible depends on the formulas downstream, and you don’t know which without checking. In a DCF model, a Monte Carlo simulation, or a pricing engine, invisible errors travel silently.
Regulatory compliance. In regulated domains, auditors typically expect calculations to be reproducible, which regime applies and what exactly it demands varies, but “the model sampled a slightly different number this run” satisfies none of them. An LLM that returns slightly different results on each run, because it’s sampling, not computing, fails that expectation by design.
Trust erosion. Once a team discovers that their “AI-powered analytics” produced subtly wrong numbers, trust in the entire system collapses. The damage isn’t the error itself, it’s the realization that you can’t tell which numbers are right.
The Architectural Fix: Push Calculations Down
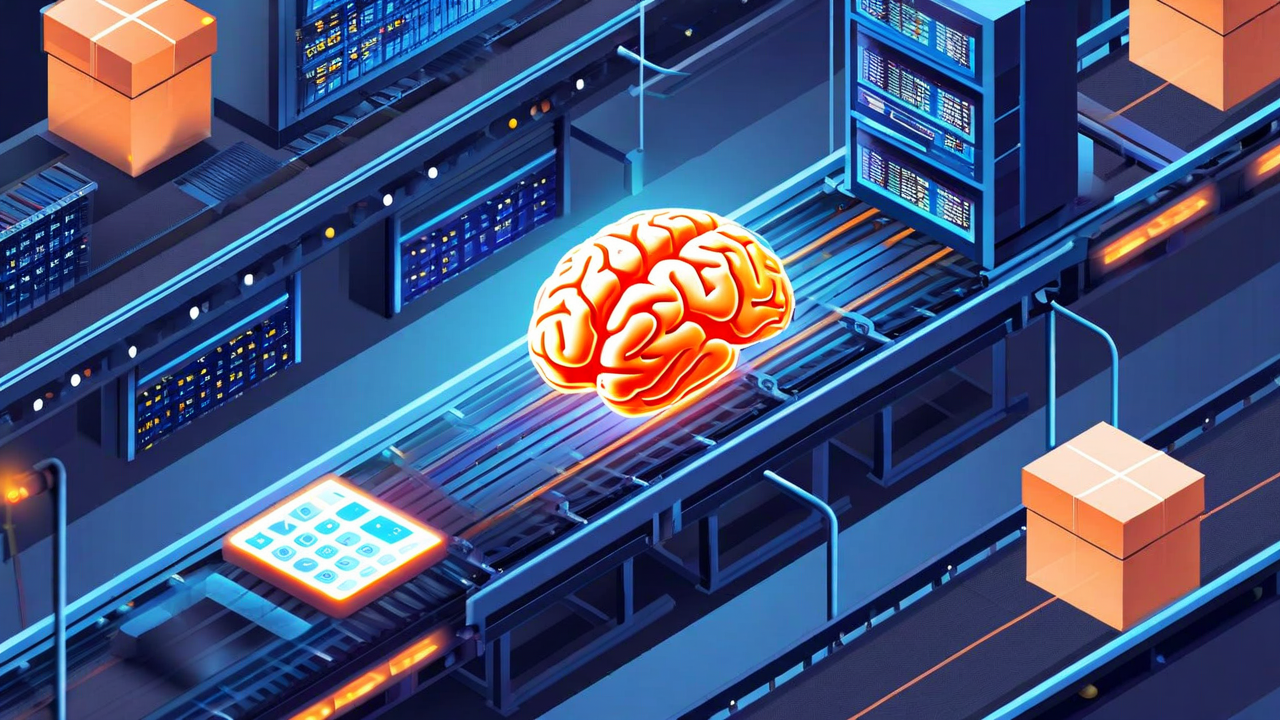
The LLM interprets. Specialized systems calculate. Clean outputs emerge.
The solution isn’t to make LLMs better at math. It’s to stop asking them to do math.
The principle is simple: let the LLM think, let deterministic systems calculate. The LLM handles natural language understanding, interpreting what the user wants. The actual computation happens in a system designed for it.
There are two ways to implement this:
Option 1: Code Interpreter (Generated Scripts)
The LLM writes a Python script, executes it, and reads the result. This is what ChatGPT’s Advanced Data Analysis does. It works, the LLM effectively “checks its work” by using a calculator rather than its own brain.
Pros: Flexible, no infrastructure needed, handles ad-hoc calculations. Cons: You’re trusting the LLM to write correct code. The generated script might have bugs, edge cases, or wrong assumptions. Each query generates throwaway code that’s never reviewed. It’s a workaround, not an architecture.
Option 2: Dedicated Analytics Systems (via Tool Use or MCP)
The LLM translates the user’s question into a query against a dedicated system, a BI engine, a database, a spreadsheet engine, that performs the actual calculation. The LLM interprets and presents the results but never touches the numbers.
On AWS, this maps cleanly:

The LLM understands intent. Athena and QuickSight do the math.
- Data in S3 → query via Athena (SQL, deterministic, auditable)
- BI dashboards → query via Amazon QuickSight, which now supports MCP clients, letting AI agents query the business metrics your organization has already defined and governed [2]
- Custom calculations → Lambda functions called via Bedrock tool use, reviewed, tested, version-controlled code
Pros: Deterministic, auditable, reproducible, properties you get by keeping the calculation logic in reviewed, versioned code or a governed query engine; the services provide the platform, your engineering discipline provides the guarantees. Scales to production. Cons: Requires infrastructure. You need the data pipeline, the query engine, the tool integration.
When to Use Which
| Scenario | Approach |
|---|---|
| Ad-hoc exploration, prototyping | Code interpreter, fast, flexible |
| Production analytics, financial reporting | Dedicated system, deterministic, auditable |
| Customer-facing calculations | Dedicated system, you can’t ship throwaway scripts |
| One-off data analysis | Code interpreter, good enough |
The key question: would you let an unreviewed script calculate your quarterly revenue? If not, you need a dedicated system. The code interpreter is a powerful prototyping tool, but production calculations need production infrastructure.
The Broader Lesson
To be precise: LLMs can do simple arithmetic correctly, 7 × 8 = 56 works because that pattern is overwhelming in training data. The more accurate statement is that next-token generation doesn’t execute the arithmetic, it predicts the result. For simple patterns, prediction and computation produce the same result. For complex, multi-step calculations, they diverge.
This isn’t just about spreadsheets. It’s about understanding what LLMs fundamentally are: prediction engines, not calculators. Every time you use an LLM for a task that requires deterministic, reproducible, exact results, math, date calculations, data lookups, code execution, you’re relying on prediction where you need computation.
Some models are already internalizing this lesson. Gemini’s built-in code execution and ChatGPT’s Advanced Data Analysis both separate the thinking from the calculating: the model writes code, and a runtime executes it, deterministic in the same-input-same-output sense, with numerical accuracy still bounded by the generated code and its floating-point arithmetic. That’s the right architecture, applied internally. The article argues you should apply the same principle explicitly in your own systems.
The question of “good enough” depends entirely on the stakes. A 0.3% error in a blog post is fine. A 0.3% error in a clinical trial dosage calculation, a financial audit, or a structural engineering model can mean a finding under whichever standard governs that work, or worse. Know your tolerance, and architect accordingly.
The fix is always the same shape: give the LLM a tool. Let it reason about the problem, then hand off the execution to something deterministic. The handoff moves the trust, it doesn’t remove it, the tool itself needs to be tested, its inputs validated, and for high-stakes outputs, independently checked.
💬 Have you encountered invisible AI math errors in your work? How did you catch them?
Sources
[1] GRID, “Numbers don’t lie, but AI might”: grid.is
[2] AWS, “Connect Amazon Quick Suite to enterprise apps and agents with MCP”: aws.amazon.com
[3] My hands-on experiment with self-reflection on Bedrock, “When Thinking Twice Helps, And When It Doesn’t”: schristoph.online
[4] Amazon Bedrock Pricing, on-demand rates, prices at the time of writing (March 2026): aws.amazon.com
About the Author
Stefan Christoph is a Principal Solutions Architect at AWS, focused on agentic AI, media & entertainment, and helping builders move from demo to production. He writes about AI architecture, developer productivity, and the future of software.
This is a personal blog. Opinions expressed here are my own and do not represent the views or positions of my employer.