

Laws & Disorder · 8 min read
Laws & Disorder #3 — Tesler's Law: You Can't Delete Complexity, Only Choose Who Owns It

Laws & Disorder — Part 3 of 6
On this page
Third in “Laws & Disorder.” After Conway’s Law and Hyrum’s Law, here’s the one that quietly decides every build-vs-buy argument.
There is a comforting lie in a lot of architecture decks: this design is simpler. Sometimes it is genuinely simpler for you. But the total amount of complexity in the problem usually did not shrink. It moved. Somebody, or some service, is now holding the part you stopped holding.
That is Tesler’s Law, and it turns build-vs-buy from a gut call into a clear question about who owns what.
The law
Larry Tesler, working on early graphical interfaces at Apple in the 1980s, formulated the conservation of complexity: every application has an inherent amount of complexity that cannot be removed, only shifted [1]. It is worth reading that as the design heuristic it is rather than as a physical law, because the boundary condition matters: complexity is conserved for a given set of requirements. Someone still has to absorb the difficulty of the job the software actually does, and you get to choose whether that is the user, the developer or the operator. Change what the software is required to do, drop a feature, narrow the scope, pick a problem formulation that admits a simpler algorithm, and complexity genuinely leaves rather than moving. That is not a loophole in the law; it is the one lever the law does not cover. Simplify one layer and another layer absorbs the difference. A scheduling tool that finds a free slot for you did not delete the time-zone math and the conflict-checking. It absorbed that complexity internally so you would not have to hold it [1], [2], [3].
It rhymes with Fred Brooks’s older distinction between essential and accidental complexity: some complexity is inherent to the problem and cannot be designed away, while some is incidental to how we built it [4]. Tesler’s point is about that essential floor. You cannot get under it. You can only decide where it lives.
The two complexities most people conflate
Here is the distinction that makes the law practical, and it is the spine of this post. When you build a system there are two different quantities in play, and they are not the same:
- (A) the total realized complexity of the whole system, the inherent complexity the requirements demand, plus whatever the implementation adds on top, and
- (B) the complexity you personally have to manage and operate.
Good architecture optimizes B without carelessly blowing up A. Most bad build-vs-buy decisions come from optimizing one of these while forgetting the other exists.
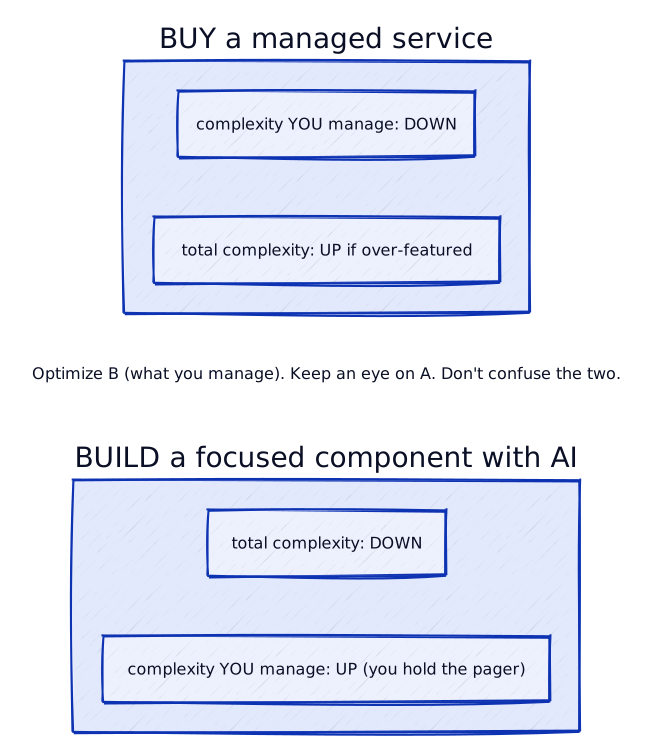
Buy shrinks what you manage. Build-with-AI shrinks the total. Optimize what you manage; watch the total.
The offload move: managed services shrink what you manage
The cleanest way to reduce B is to hand a slice of your system to someone who runs it well. When you move a self-managed database onto Amazon Aurora, or a self-managed cluster onto EKS with Fargate, or an always-on server onto Lambda, you are not deleting the complexity of running that thing. You are giving it to a team whose entire job is to run it, and who run it at a scale most teams would struggle to match. Much of the undifferentiated heavy lifting, patching, failover, capacity, leaves your plate, with the exact split depending on each service’s shared-responsibility line [5].
I want to be direct about the framing here, because it is easy to get backwards: this is a win, not a compromise. Moving to a managed service is one of the best tools you have for managing complexity, precisely because it shrinks the complexity you own without pretending the complexity vanished. The complexity is conserved. It just lives with the party best equipped to carry it. That is the whole point of the cloud, and it is a good point.
The counter-trap: don’t inflate the total
There is a matching failure mode, and it is subtler. A managed component still adds to your system’s total complexity (A), even though you do not operate it. If you reach for a service that is far more capable, and far more complex, than your need requires, you have lowered B nicely but quietly raised A. Now your architecture carries features, failure modes, and conceptual surface area you never use, and that surface leaks into everything that touches it. A managed component you did not right-size is still complexity in your system.
So the offload move has a discipline attached: pick the service that fits the need, not the most powerful one available. Reducing what you manage is good. Doing it by bolting on something oversized is how you win on B and lose on A.
The AI twist: build leaner, own more
Now the forward-looking part, and I’ll mark it clearly as my reasoning as of 2026 rather than settled fact.
AI changes the build side of the trade-off. It is now cheap to generate a focused component that does exactly what you need and nothing more, cheap to write, that is; verifying, testing and maintaining it remains a separate bill. A general-purpose product bundles features for a thousand customers; a component you generate for your one use case can carry far less inherent complexity, because it does not have to serve everyone. In Tesler’s terms, building the focused thing can lower the system’s total complexity (A), because the thing itself is genuinely smaller.
The catch is on the other axis. The moment you build and run that component, you own it. You hold the pager. Running it on managed infrastructure softens the operations but not the ownership, the logic, the bugs, and the upgrades stay yours. You patch it, you scale it, you debug it at 2 a.m. So building with AI can lower A while raising B, which is the mirror image of the managed-service move that lowers B while possibly raising A.
That reframes the classic build-vs-buy decision cleanly:
- Buy a managed service, and you have less to manage (B down), possibly more total complexity if it’s over-featured (A up, the requirements did not change, the realized system grew).
- Build a focused component with AI, and you get less total complexity (A down), but more to manage because you operate it (B up).
The trap to avoid is optimizing only for the total. It is tempting, because a lean custom component looks so elegant on the diagram. But in the end the complexity you manage is what sets your operational load, your on-call burden, your ability to sleep. Do not ignore B to chase a smaller A. And do not ignore A either. Neither number is the whole story, which is exactly why naming both is the useful move.
If you’re running this on AWS
- Judge every component on both axes. Ask “does this reduce what I manage?” and “does it keep total complexity in check?” separately. A choice can be great on one and bad on the other.
- Right-size the managed service. Prefer the service that fits the need over the most capable one. Lambda hides infrastructure but surfaces an invocation model to reason about; that trade is worth it when it fits, and a tax when it doesn’t [5].
- Own deliberately. If you build a focused component with AI, budget for operating it. The build was the cheap part; the pager is the recurring cost.
- Keeping complexity can be right. Choosing to self-manage something because you need the control is a legitimate decision, not a failure. It just means you’ve chosen to own that complexity on purpose.
Complexity is conserved once the requirements are fixed. Your job is usually not to make it disappear, because at fixed scope you can’t, you can only decide who carries it. Your job is to decide, on purpose, which parts you carry and which parts you hand to someone who carries them better.
When you last called a design “simpler,” did the total complexity actually shrink, or did you just move it somewhere you’ll pay for later?
More in this series
Follows Hyrum’s Law (complexity you push into a component still leaks observably) and leads into Gall’s Law (complexity you can’t delete, you also can’t design away up front). Sparked by the Laws of Software Engineering collection [6].
Sources
- [1] Law of conservation of complexity, Wikipedia, Tesler’s principle, its Apple origin, and the shift-not-delete statement.
- [2] Farnam Street, Why Life Can’t Be Simpler, the idea applied beyond software.
- [3] Humanist.co, Law of Conservation of Complexity, a design-focused explainer.
- [4] No Silver Bullet, Essence and Accident in Software Engineering (Brooks, 1986), the original paper on essential vs accidental complexity (Wikipedia summary).
- [5] AWS Lambda, how it works, a managed service that absorbs infrastructure while surfacing an invocation model to design around.
- [6] Laws of Software Engineering, Tesler’s Law, the collection that sparked this series.
Cross-posted to LinkedIn
🎬 Also available as a blog walkthrough video on YouTube
❤️ Created with the support of AI (Kiro)
📝 Last updated: August 17, 2026 — Technical corrections from a quality audit; Editorial polish for readability and voice